<?xml version="1.0" encoding="utf-8"?><feed xmlns="http://www.w3.org/2005/Atom" ><generator uri="https://jekyllrb.com/" version="3.10.0">Jekyll</generator><link href="https://pulkit.cc/feed.xml" rel="self" type="application/atom+xml" /><link href="https://pulkit.cc/" rel="alternate" type="text/html" /><updated>2026-07-16T21:38:39+00:00</updated><id>https://pulkit.cc/feed.xml</id><title type="html">Pulkit Sharma</title><subtitle>Pulkit Sharma&apos;s Personal Blog and Opinions
</subtitle><author><name>Pulkit Sharma</name></author><entry><title type="html">You Can’t Lose If You Didn’t Set Out To Win</title><link href="https://pulkit.cc/2025/03/31/spelltastic/" rel="alternate" type="text/html" title="You Can’t Lose If You Didn’t Set Out To Win" /><published>2025-03-31T21:46:50+00:00</published><updated>2025-03-31T21:46:50+00:00</updated><id>https://pulkit.cc/2025/03/31/spelltastic</id><content type="html" xml:base="https://pulkit.cc/2025/03/31/spelltastic/"><![CDATA[<p>Having constantly working on the backend side of tech, I would often find myself deeply insecure about my frontend coding skills. As time went by, I started getting deeper into networking protocols, containers, databases, platform engineering AND at the same time, I was getting farther away from React, NextJS, and frontend development in general.
To keep it short, I challenged myself to create a full blown application, deploy it on a cheap VPS and then see if I can get some traction and earn some internet dollars. I wanted to build it anonymously and did not want to use my existing network on LinkedIn to get users, as I knew most of them will just use it once and never become a “customer”. The interesting (or rather disappointing) bits start once I had the product built and now I was ready to launch it. Here it goes…</p>

<h2 id="building">Building</h2>
<h3 id="the-idea">The Idea</h3>
<p>My core idea was very simple: find spelling mistakes in websites.
This is a relatively straightforward problem and with the help of latest LLM models (which are very good at finding spelling mistakes) I should be able to create a good enough solution. In case this gets famous, I could probably expand into more areas.</p>

<h3 id="the-polish">The Polish</h3>
<p>Just the core idea was very simple to implement, so I wanted on rest of the “product” to be really good looking and polished, something which I have vehemently avoided throughout my career working primarily on the backend. My mind was constantly thinking about offloading this task to some freelancer on Upwork so I can work on the “core” features, but then I forced myself to actually work on the product as that was my initial goal: make a good looking and usable product, not just a highly scalable LLM powered spell checking engine written in Go.</p>

<p>Some of these non-core functionalities I decided on were:</p>
<ul>
  <li>Taking a screenshot of the problematic section on the page and highlighting the mistakes with a red underline.</li>
  <li>Generating suggestions/corrections via LLM.</li>
  <li>Asking LLM to assign a severity score to each mistake.</li>
  <li>A simple shareable report URL which can be sent to the user.</li>
  <li>Full blown user management / dashboard to track, schedule, and manage scans.</li>
</ul>

<h3 id="implementation">Implementation</h3>
<p>I heavily utilised Cursor for designing and coding the application. I chose NextJS as the development framework, as it was completely new to me. Having the same codebase for both the frontend+backend with all the bells and whistles was pretty enticing.
I rented a very cheap VPS (5 euros per month) from Hetzner and after some experimentation decided to use PM2 for serving the NextJS application. For deployment, I utilised Github Actions to deploy to the VPS after merging to the <code class="language-plaintext highlighter-rouge">main</code> branch:</p>

<p>The other components/libs used were:</p>
<ul>
  <li>Sqlite
    <ul>
      <li>for storing users, scan results, credits, etc.</li>
    </ul>
  </li>
  <li>Redis (running locally, via systemd)
    <ul>
      <li>For caching the DOM tree of the pages and LLM requests.</li>
    </ul>
  </li>
  <li>Clerk
    <ul>
      <li>For Authentication, “Sign In Via Google”</li>
    </ul>
  </li>
  <li>Puppeteer
    <ul>
      <li>For extracting text from a website, highlighting errors, and more.</li>
    </ul>
  </li>
  <li>Dodo Payments
    <ul>
      <li>MoR provider based in India for handling payments.</li>
    </ul>
  </li>
  <li>TailwindCSS
    <ul>
      <li>I have to admit, 99% of tailwind was written by Cursor. Just CMD+K the div and say how you want it to look.</li>
    </ul>
  </li>
</ul>

<h3 id="issuesroadblocks-possible-skill-issue">Issues/Roadblocks (possible skill issue)</h3>
<p>The NextJS ecosystem at that time (around Dec 2024) seems to be heavily inclined towards using PaaS tools like Vercel, Render, etc. The documentation / guides for deploying a simple application on a VPS were not great (comparing to something like Ruby on Rails).</p>

<p>Some other issues I faced:</p>
<ul>
  <li>API Support: It feels like NextJS is targeted more towards web development instead of just pure API development. My initial plan was to utilise an API in the frontend and use the same API to expose to customers who may want to use the product directly via API. Implementing this is possible, but there is a lot of duplicate code in each API handler (for authentication, context setting, permissions, etc).</li>
  <li>Documentation: Several times I ended up spending time in reading and writing code which was incorrect as I was referring to an incorrect “Router” implementation. Some of the google searches go to the “App Router” docs and some of them go into the “Page Router” docs. After days, I made it a habit to first check if I am reading the correct documentation.</li>
  <li>Logging in NextJS: Once you build a production bundle, the app stops logging the requests/responses. Some custom loggers/middleware updates have to be done in order to get the logging back.</li>
  <li>Middleware Runtimes: The runtime for middleware is “different”, some node packages can be used and some cannot. I did not find the middleware usage intuitive and was constantly confused on which kind of params to accept in the method.</li>
  <li>Related to above: I felt that Cursor sometimes was creating code which was in the incorrect “Router” mode. And the errors did not help much this.</li>
</ul>

<h2 id="launch-growth-hacking-and-feedback">“Launch”, “Growth Hacking” and Feedback</h2>
<p>I spent a lot of time on reading and watching videos on “Launching” and “Growth Marketing”. It seems like Product Hunt was the place to go, and then some newer alternatives like Uneed, Peerlist. I created a twitter account for my product. My plan for marketing was to scan famous websites for spelling mistakes and then tag them in a tweet -&gt; they would notice it and possibly reply with a “thanks” -&gt; and this way I will get visibility and then my product will spread by “word of mouth” and soon I will be cashing in dollars ! :-D  That was my plan atleast..</p>

<h3 id="twitter">Twitter</h3>

<p>I created a new twitter account and I am pretty sure it was/is probably under shadowban, I did not get a single reply, I was finding genuine mistakes in landing pages, docs and more. Continuing further was the hardest, and with no feedback, I was not motivated to continue. So as is pretty common, I thought I need to build more features :-D , so I spent another 2-3 days quickly creating a chrome extensions to allow scanning webpages without coming to my website. I also created a blog section and wrote one blog which I thought would definitely gain some traction.</p>

<p>But all this was not generating a single visit on my website. I had a free no sign-up required scanning service, still no one was scanning their website. I then started DMing indiehackers with issues found on their website, and luckily I got some replies thanking me (but no signups). I then reached out to builders with really small following &lt; 1k, hoping they would be more responsive, but that wasn’t the case.</p>

<h3 id="reddit">Reddit</h3>
<p>After some days I got an idea to do a “free page scanning” post on one of the sub reddits for indiehackers and builders. That post got pretty good response, I scanned close to 30 websites. The product was working, the people were happy with the issues it was finding but again no one actually signed up :-(</p>

<p>Eventually I posted again on Reddit to get some guidance around the product and how to launch it. I got some really good and constructive feedback. The common theme here was “vitamin vs painkiller” analogy, almost everyone felt that this product is a vitamin and not a painkiller. And they were right, I found several landing pages with some mistakes, but those were not “critical” mistakes in order to catch anyone’s attention. Most of the product on a baseline had good enough “copy” (that’s what they call the “text” in the marketing world).</p>

<h3 id="product-hunt-and-the-growth-hacker-call">Product Hunt and The Growth Hacker Call</h3>
<p>Without any other option in sight, I decided to launch on Product Hunt (and similar alternatives). That’s when I realised the sheer amount of products which are being launched everyday…do people use these ? Are there so many people searching for new products everyday ? voting, commenting on products, giving feedback ?</p>

<p>It was pretty overwhelming to see big well funded companies launching products everyday. How will I compete with them ? Most of the products already had tons of users, very rarely were there products from unknown names / solo devs or with zero users. Some products were being launched again after a launch done an year ago. 
The only thing I could understand from all this was the need for someone to “hunt” your product. If one of these product hunters hunt your product (According to PH) there is a good chance that more people will notice you. That’s exactly what I wanted, I wanted to be noticed !</p>

<p>So I reached out to one very famous growth hacker / product hunter on LinkedIn and we connected over a call. He gave some good inputs, but eventually it came down to the “offerings”. They had different packages, under some packages they would create high quality Reddit posts from high Karma users to boost visibility and under some they would completely take over your marketing (SEO, blogs, etc), other ones would provide high quality backlinks to the website. There were lots of “tactics” under this so called “Growth Hacking” strategy and according to him that’s the only way to get a new unknown product out in the world.</p>

<h2 id="vibe-coding-bike-shedding">Vibe Coding Bike Shedding</h2>

<p>After the call with the growth hacker, I decided it’s time to make the product really good, I won’t fall for these cheap growth tactics (not actually cheap, they cost $$$).</p>

<p>So anyways I did not stop at just making a basic Chrome Extension, I went on to create screenshots, demo videos, and logo for the extension.</p>

<p>I did some more iterations on the landing page, I thought I am not getting users because the feature descriptions are missing nice logos or maybe I am missing an FAQ section or maybe my pricing page is not looking good on a mobile device..</p>

<p>In a non-AI world, I would not have spent so much time on these useless improvements, as it takes a lot of time to do changes on the UI (for me), but armed with a paid 1 year Cursor plan, I was not going to stop..</p>

<p>Basically with frontend there is a lot of trial and error involved to get things to look how you imagine it in your head. That’s not the case for me when writing non-web code (like an API endpoint, CLI, script, SQL, etc), you sort of know the exact way things will work (barring some non determinism due to infra related issues for instance). Maybe experienced frontend developers can just write tailwindCSS code and it works the first time in the browser, but for me it’s a lot of trial and error (even with the help from Cursor).</p>

<p>But because of Cursor, I was just acting like a frantic product manager asking my dev team (me) to do random changes on the frontend. Like create a toggle for dark mode etc, I thought these things were easy to implement, just change some CSS variables and BOOM now your entire website is in dark mode… But no, that’s not how it works..</p>

<p>I was going to dive into A/B testing my landing page but thankfully I stopped and then I did a course on SEO with NextJS :-) . I created dedicated pages, like “free landing page scanner”.</p>

<p>I integrated OpenGraph meta tags to create link previews for reports, blogs and other sections of the page. I wanted my imaginary users to have a good experience when they would share my reports in their non existing company Slack channels… All this because of Cursor, it fed my ADHD all day everyday and kept my dopamine receptors fried.</p>

<p>I scanned some more websites and sent cold emails to some of the founders/agencies who were building in public, in order to get their attention. I create a new LinkedIn account and reached out to some web dev agency owners, but none replied. I spent a lot of time to go through their projects, find their org structure, and determine the correct people to reach out to.</p>

<p>At one point I had to resist the urge to automate the entire chain:</p>

<ol>
  <li>get newly launched websites from ProductHunt.</li>
  <li>Scan their landing pages.</li>
  <li>If there are any issues found, create a publicly shareable link.</li>
  <li>Fetch email ids from Apollo or similar websites.</li>
  <li>Send them a personalised email with the link to their report.
    <ul>
      <li>utilising LLMs for create the mail content etc.</li>
    </ul>
  </li>
  <li>Add tracking params to these links and send an alert if someone visits / creates an account etc.</li>
</ol>

<p>I was going to vibe code this away, but then I stopped.</p>

<h2 id="giving-up">Giving Up</h2>
<p>I did a “Show HN” on HackerNews as one last attempt to get some traction and as you might have guessed, it did not get any attention. I did not want to spend more time on marketing the product, as all those felt shots on the dark.</p>

<p>My learnings from this project has reinforced what I knew theoretically from countless other blogs posts and tips:</p>

<ul>
  <li>Building a product is not the hard part in most cases, it’s getting users to use it and even harder: getting users to pay for it.</li>
  <li>So get users first before building anything. I don’t have any answer or secret formula for this. Most of the times the users are not searching for a product. It depends on a lot of factors.</li>
  <li>Do not build something which you will not use yourself.</li>
</ul>

<h3 id="open-sourcing">Open Sourcing</h3>
<p>After making exactly 0 dollars (and spending around 20 dollars on domain, infra &amp; LLM tokens), I decided to stop working on it further. On the bright side I learnt a lot of things around web development, UI/UX and marketing. I never had any big hopes to begin with, so I did not feel like some kind of failure at the end of this all. If this would have taken off, I would be really happy with it. If you are interested here is the Github Repo: <a href="https://github.com/pulkitsharma07/spelltastic.io">https://github.com/pulkitsharma07/spelltastic.io</a> and the website is live here: <a href="https://spelltastic.io">https://spelltastic.io</a>.</p>

<p>If you plan to build something using this or want to discuss some other ideas, please reach out to me !</p>

<h3 id="is-this-blog-part-of-the-growth-strategy-for-the-product-">Is this Blog part of the growth strategy for the product ?</h3>
<p>Good point ! But, No. This post is not in any way to get any growth for my product. I am writing this blog to document my journey and learnings from this project, writing a retrospective post at the end of it all was always my goal. If anything, this blog post is a growth strategy for my personal brand, so that people can know the kind of things I have worked on / built / regretted and my thought process behind those. This blog post is being written to close the loop on this entire thing.</p>]]></content><author><name>Pulkit Sharma</name></author><category term="personal" /><summary type="html"><![CDATA[A tale about a side-project which I built to learn more about frontend development and marketing.]]></summary></entry><entry><title type="html">My Experience with Cursor</title><link href="https://pulkit.cc/2024/12/30/cursor/" rel="alternate" type="text/html" title="My Experience with Cursor" /><published>2024-12-30T04:30:00+00:00</published><updated>2024-12-30T04:30:00+00:00</updated><id>https://pulkit.cc/2024/12/30/cursor</id><content type="html" xml:base="https://pulkit.cc/2024/12/30/cursor/"><![CDATA[<h2 id="cursor---the-ai-editor">Cursor - The AI Editor</h2>
<p>A little background, For those who are not aware <code class="language-plaintext highlighter-rouge">Cursor</code> is an AI-first fork of the very popular Visual Studio Code editor. More info <a href="https://www.cursor.com/">here</a>.
I guess I am late to the party, but I never really gave any of these AI IDEs a shot…until now.</p>

<h1 id="a-new-codebase">A New Codebase</h1>
<p>At work, we were exploring approaches to quickly spawn up nodes in one of our K8s cluster. The Windows EC2 machines in particular take a looong time to boot up ( &gt; 15 minutes sometimes). Although AWS provides <a href="https://docs.aws.amazon.com/AWSEC2/latest/UserGuide/win-ami-config-fast-launch.html"> Windows FastLaunch</a>, but it has limitations on how frequently you can launch new machines and the boot up time was still quite high for our usecase.
In k8s, the component which spawns new nodes when needed is the <code class="language-plaintext highlighter-rouge">autoscaler</code>. It is written in Golang (as most of the K8s codebase) and calls the underlying cloud provider APIs (AWS, GCP, Azure etc) to spawn new nodes when needed, i.e. when there are pending pods in the cluster. Another well known auto-scaling solution for K8s is <code class="language-plaintext highlighter-rouge">Karpenter</code>.</p>

<p>I had proposed an idea to the team to patch <code class="language-plaintext highlighter-rouge">autoscaler</code> for our custom usecase. I had never contributed to any K8s internals before, so all of this was pretty new to me.</p>

<p>So, there were three approaches for me to move ahead:</p>
<ul>
  <li>I take some time to understand the codebase and find the relevant methods that I can modify.</li>
  <li>Or use some AI flavor-of-the-month tool to aid in the same.</li>
  <li>Or try to play whack-a-mole by searching random terms relevant to my task, something very common if you are into reverse engineering.</li>
</ul>

<h3 id="starting-with-the-old-skool-way">Starting with the Old Skool way</h3>
<p>I went ahead with the third approach as sometimes it gets the job done real fast. A Good ol full-text search using <code class="language-plaintext highlighter-rouge">ag</code> over the entire codebase with some keywords which I felt could be related to my task: <code class="language-plaintext highlighter-rouge">scaleup</code>, <code class="language-plaintext highlighter-rouge">AddNode</code>, <code class="language-plaintext highlighter-rouge">SpawnNode</code>, etc.</p>

<p>Eventually, I found some interesting code areas, so I went into VSCode to understand the code flow further. Using the <code class="language-plaintext highlighter-rouge">Go To Definition</code> and <code class="language-plaintext highlighter-rouge">Go To References</code> bindings I was able to quickly get a good overview of the call hierarchy and started to develop some mental image of the code base.
But I was still not sure I was looking at the correct code area for the thing I wanted to achieve, after 10-15 minutes I eventually noticed <code class="language-plaintext highlighter-rouge">../oci/..</code> in one of the file paths I was checking… Apparently, I had spent the last 30 minutes reading code that was completely irrelevant to my use-case, here oci = Oracle Cloud Infrastructure. While going blind into a new codebase the file path may sometimes convey <em>more</em> information than the file contents…</p>

<p>I then looked into the codebase under the <code class="language-plaintext highlighter-rouge">../aws/..</code> directory and eventually, I found a relevant method that seemed to be something related to what I wanted to do.. but I still wasn’t sure, the method was more than 100 lines long.</p>

<p>I tried to eyeball sections of the code, looking at just variable names and function names to quickly develop some crude understanding of the flow. Then I thought… AI ….Why not use use the AI magic here, we have tools for this now. Since my Github Copilot trial had expired, I wanted to give <code class="language-plaintext highlighter-rouge">Cursor</code> a shot.</p>

<h3 id="enter-cursor">Enter: Cursor</h3>
<p>Installing Cursor was blazing first, I opened the codebase, and all of my existing VSCode extensions were installed automatically and I was already in Vim mode, nice. I quickly opened the file I was checking out earlier and went straight to the function. And that’s when I noticed the Cursor prompt: <code class="language-plaintext highlighter-rouge">Cmd+L to generate, Cmd+K to chat</code>, without thinking twice I selected the entire method in visual mode -&gt; <code class="language-plaintext highlighter-rouge">cmd+K</code> -&gt; <code class="language-plaintext highlighter-rouge">"Explain this and let me know if this is the right place to do &lt;my task&gt;"</code> .. almost instantly I got a summarized version of that 100 line method and I got confirmation from Claude (the underlying LLM) that I was on the right track.</p>

<p>Next, I wanted to check if Cursor understands the call hierarchy of this method and eventually how this method is invoked by the autoscaler. I am not sure how many tokens it consumed, but yes it did give me some information but it was not exactly correct, there were some methods that it mentioned that were not actually present in the codebase.
But I was not expecting it to be correct in the first place. Most of the things it mentioned were correct and now I had a very basic understanding of the scale-up phase of the autoscaler.</p>

<p>On this day, Cursor had saved me around 30-40 minutes of dev effort. The rest of the coding had to be done manually, as I had to make changes in multiple files (update interfaces, change method signatures, etc), I was not really sure how to prompt Cursor for these use cases. Plus the overall codebase was quite big, so I am not sure how would Cursor do RAG just based on my prompts. Maybe I could provide a detailed prompt with which it could select the relevant files. But I felt it would be faster (and less error-prone) to just do those changes manually as I knew what I had to do.</p>

<p>Plus Go being a language with excellent VSCode support (and documentation), writing code in it is always a breeze.</p>

<h1 id="powershelling-with-cursor">PowerShelling with Cursor</h1>
<p>To ensure my proposal around patching autoscaler works, I had to make sure that some interactions between the autoscaler and Windows EC2 node work properly. After some chatgpting and googling I was now ready to tweak the <code class="language-plaintext highlighter-rouge">userdata</code> script for Windows (generated by EKSctl). This <code class="language-plaintext highlighter-rouge">userdata</code> script configures the EC2 machine to join the K8s cluster on boot (and also does some config related tasks/cleanup). For Windows, this script was written in <code class="language-plaintext highlighter-rouge">PowerShell</code>, and this is when I became a fan of Cursor.</p>

<h3 id="programming-in-natural-language">Programming in Natural Language</h3>
<p>This time I utilized the <code class="language-plaintext highlighter-rouge">Cmd+L</code> shortcut in Cursor, and I just gave it instructions on things I wanted to do. I was not sure how to create <code class="language-plaintext highlighter-rouge">systemd</code> like services that run on reboot in Windows, so I just asked Cursor to do that. I was not sure if powershell even supported functions, So I asked Cursor to just create a function for logging and call it in relevant places. It generated the function and also updated the script to call that function.</p>

<p>Not having to do the loop of: goto browser, goto chatgpt/google/stackoverflow, type query, read, select the relevant part of code (if any), copy, paste in editor, refactor/rename variables… was a real time saver. Especially with PowerShell which I had zero experience of.</p>

<h3 id="seeing-cursor-think">Seeing Cursor Think</h3>
<p>Another feature I loved about Cursor is the way it processes large chunks of code, it highlights each line as it is processing it, editing it only if it is required to do so. Instead of dumping your entire code into an LLM and replacing it with the response, it seems Cursor is doing something more “intelligent”. It goes over each line (or batches of lines) and highlights it neatly as it is doing so. It suggests the edit as a git diff which you can apply or reject… and then you continue a conversation while it keeps track of the diffs internally.</p>

<h3 id="less-tech-debt-with-higher-speed">Less tech debt with higher speed</h3>
<p>This reads like an ad, but using Cursor really helped me to reduce tech debt in my code. Traditionally, I would write copious amounts of <code class="language-plaintext highlighter-rouge">TODOs</code> in my code, as I don’t find it relevant to spend time on things that are not actually making a noticeable impact in the short term. With Cursor, instead of leaving <code class="language-plaintext highlighter-rouge">TODOs</code> in the codebase, I can just ask it to do it. For example, I asked it to <code class="language-plaintext highlighter-rouge">Move all logging behind an environment variable named DEBUG</code>.</p>

<p>At this point, I had easily saved about 5-6 hours of effort (and pain) in writing Powershell scripts and corner cases around reboots, string escaping, and exit codes. This saving may seem small, but I think it helped me deliver the final implementation 2-3 days earlier than planned, which is a lot since I had planned to deliver everything under two weeks.</p>

<h3 id="better-readme">Better Readme</h3>
<p>One unexpected win for Cursor was writing documentation(<code class="language-plaintext highlighter-rouge">README.md</code>). I like writing detailed documentation around anything I work on. I never really thought about how predictable or “LLMable” this task is. With just a few words Cursor (or rather Claude) was able to suggest what I wanted to write. It felt stupid to not accept the suggestions. Of course, some suggestions were wrong, I can just write those things, I am not expecting it to complete the entire documentation on its own. Overall I saved a lot of time writing the readme and I re-invested this saved time into it again to make the documentation even better.</p>

<h1 id="final-thoughts">Final Thoughts</h1>
<p>Having AI integration right into the IDE is a game changer. Dealing with “text” is what LLMs are great at and coding is just “text” data, so IMO AI will have a massive impact on coding (especially via these AI-first IDEs). I don’t think this positively about tools like Devin which claim to do pretty much anything related to coding. I am willing to bet that tools that improve humans will actually thrive more than the tools that aim to replace humans.</p>

<p>Using Cursor was a massive productivity boost for me which I had not really anticipated (even after using ChatGPT extensively), and I am happy to recommend it to any developer who has considerable coding experience. As for new developers, please stick to non-AI tools for now as it can really hinder your learning experience.</p>]]></content><author><name>Pulkit Sharma</name></author><category term="personal" /><category term="learning" /><summary type="html"><![CDATA[Cursor - The AI Editor A little background, For those who are not aware Cursor is an AI-first fork of the very popular Visual Studio Code editor. More info here. I guess I am late to the party, but I never really gave any of these AI IDEs a shot…until now.]]></summary></entry><entry><title type="html">About ‘Permutation City’</title><link href="https://pulkit.cc/2024/12/23/permutation-city/" rel="alternate" type="text/html" title="About ‘Permutation City’" /><published>2024-12-23T04:30:00+00:00</published><updated>2024-12-23T04:30:00+00:00</updated><id>https://pulkit.cc/2024/12/23/permutation-city</id><content type="html" xml:base="https://pulkit.cc/2024/12/23/permutation-city/"><![CDATA[<h2 id="on-note-taking">On Note Taking</h2>

<p>While reading “The Three-Body Problem”, I developed this habit of keeping a small notebook with me to jot down key moments of a chapter. The purist inside me wanted to fight back and force myself to remember everything. Taking notes felt too “academic”.. but then I just did what I felt was making things more enjoyable rather than do something to cater to the perfectionist inside me… so I took notes.. and I also read them before I picked up the book again.</p>

<p>I found it to be immensely helpful to keep track of what was happening and saved myself from unnecessary cognitive load of remembering things in realtime (while reading). I followed the same approach with Permutation City.</p>

<h1 id="why-you-should-read-permutation-city--no-spoilers">Why you should read Permutation City ? (No Spoilers)</h1>

<p>This was my second sci-fi book. There were times where I had to keep the book down and just re-read and try to grasp what the author was conveying. These challenging bits were the most interesting to me, and it also lead me down to discover the FAQ of the book hosted online by the author (Greg Egan).</p>

<p>You should read this book:</p>
<ul>
  <li>If you have done some work around creating games or simulations.</li>
  <li>If you are interested in learning about recursion, fractals, etc
    <ul>
      <li>The book doesn’t exactly touch on these but if you are interested in these things, the concepts covered in the book might be of interest to you as well.</li>
    </ul>
  </li>
  <li>At times you question the nature of consciousness / reality.</li>
</ul>

<h2 id="if-you-have-not-read-this-book-thank-you-for-reading-this-blog-post-you-can-leave-now">If you have not read this book, thank you for reading this blog post, you can leave now</h2>

<h1 id="for-people-who-have-read-this-book-heavy-spoilers">For People Who Have Read this Book (Heavy Spoilers)</h1>
<p><em>!! Please skip this section if you are planning to read the book. !!</em></p>

<h2 id="what-i-liked">What I liked</h2>

<h3 id="experiments-on-the-copies">Experiments on the Copies</h3>
<p>I think the best part of the book were the experiments done by Paul Durham on his copy. Especially the very first set of experiment mentioned in the book where the copy is unable to escape the environment.</p>

<h3 id="public-compute-capacity">Public Compute Capacity</h3>
<p>The way people can bid for public compute capacity gave a very AWS Spot instancy feeling.</p>

<h3 id="dealing-with-both-micro-and-macro-simulations">Dealing with both micro and macro simulations</h3>
<p>While personally thinking about simulating reality, the main question we often face is: how good the simulation should be ?</p>
<ul>
  <li>(micro-simulation) Should it even simulate at the level of planck length, i.e. simulate atomic and sub-atomic particles and their interactions ? Perhaps also dive into quantum interactions ?
OR</li>
  <li>(macro-simulation) Should it stick to a level of reality which we normally perceive in our daily life with our five senses. Which is a kind of “distance culling” approach applied to our reality.</li>
</ul>

<p>This book attempts to deal with both sets of these simulation paradigms instead of just picking one over another. Hypothetically, due to the book belonging in the “sci-fi” category, the author could have easily leveraged that freedom and claim a working micro-simulation which renders a complete believable reality on all the levels (perceived and non-perceived).
But instead the author proposed a somewhat “humble” and crude set of simulations, with their own set of interesting limitations and workarounds. These imperfect simulations and software drop you in between the action of figuring things out and thinking about various improvements / shortcoming of the system overall. These were the best moments for me while reading this book.</p>

<h3 id="hiding-a-program-inside-a-program">Hiding a program inside a program</h3>
<p>This was one of the most important plot points for me. When I first stumbled upon this in the book, I thought of various ways to achieve this.. Compression ? Some kind of AST mish-mash magic ? But what was proposed in the book was even cleverer: extra dimensions. To put is simply use 3D coordinates for representing 2D data, and “hiding” the extra information in the unused 3rd dimension of the vectors.
Unfortunately the book never really expanded upon this concept. Instead this was used to convey a story of a couple, which I honestly found a bit boring. (More on that in the section below)
I have plans to create a small working demo for some simple ruby scripts. But I am pretty sure I am underestimating the efforts involved here.</p>

<h3 id="mitm-detection-using-change-in-latency">MITM detection using change in latency</h3>
<p>I am not sure about the exact state of technology (in our real world) when this book came out (1994), so I think this could be an actual implementable novel idea, this was my first time reading about this and it makes complete sense to me.
This is the way Paul finds out that there are some people intercepting his network traffic. Because of the potential additional hop in the interceptor’s network card, he notices a change in the latency numbers. I wonder how realistic this would be to use in our current life today ? I guess not, because network paths keep on constantly shifting between two IPs on the internet plus a person doing MITM can mirror the entire set of bytes and then process them instead of actually intercepting the packets. For example, in the case of snooping on optical fibers, one can bend and decode the light “leaking” out of the cable. I wonder if this would impact any timings (or error correction schemes) on the receiver’s or sender’s end.</p>

<h3 id="the-chapter-names">The chapter names</h3>
<p>Midway through the book, while reading about the book on the internet, I got to know that the chapter names were all permutations of each other :-D 
This was a really nice easter egg to discover, and ofcourse I felt dumb af discovering about this.</p>

<h2 id="what-could-be-better">What Could be Better</h2>
<p>Although it is one of the best books I have ever read, I couldn’t help but list down few things which I would expand more upon if I were to contribute to the writing process of this book.</p>

<h3 id="dust-theory">Dust Theory</h3>
<p>My understanding of dust theory: consciousness can be rendered across disconnected events in time (i.e. non-linearly) AND disconnected points in space.</p>

<p>As a thought experiment this is definitely intriguing, but this leads to numerous other possibilities:</p>
<ul>
  <li>How many such configurations are there ?</li>
  <li>Is each possible permutation of reality/time rendering a different version of a universe ?</li>
  <li>Are these universes stable ? How many of these configurations are pure noise ?</li>
  <li>With theoretically infinite amount of possible permutations, any possibility can be true. akin to the finite monkey theorem.</li>
  <li>Hence, you do not have to worry about whether you service or your clone survives or whatever happens in the past/present/future.</li>
</ul>

<h3 id="permutation-city-itself">Permutation City itself</h3>
<p>The design of the city itself was never really touched upon. I wanted to know more about Carter, the architect of the City. As the booked is name after this City, I wanted to know more about how it was made, rendered, hidden, etc.
How Paul reached out to Carter ? Did they brainstorm about different ideas ?
The details about how they were hiding some set of people in the city were very interesting (covered in the “hiding a program inside a program” point above), but then again it was never expanded upon. My understanding was that these characters were supposed to invoke some deep philosophical thoughts in the reader about love ? or life ? or our interests ? It never really struck me as profound as some other philosophical topics covered in the book.</p>

<h3 id="limited-compute-power">Limited Compute Power</h3>
<p>In the beginning there is one company which outbids everyone to buy significant amount of compute, I may be wrong, but I never quite understood what that company did with the compute power, was it just the hydropower project ? . Who were the people behind it ? What was the actual purpose ? just to run simulations for a hydropower plant ?</p>

<h2 id="closing-thoughts">Closing Thoughts</h2>
<p>I can go on about what I liked and did not like about the book, but those are just my personal opinions based on my comprehension abilities (and memory). Needless, to say this is the best book I have ever read. Scifi books like this provokes thought as well as inspires me to write.
I think this quote from a reader from <code class="language-plaintext highlighter-rouge">r/gregegan</code> gave my good direction to think in:</p>
<blockquote>
  <p>Permutation City was my first Egan read and I can only awe at the ideas and their execution. Interpretation has never seemed necessary for me to enjoy the novel.</p>
</blockquote>

<blockquote>
  <p><a particular="" character=""> acting this way is a metaphor for something rather than an explanation for the reader to decipher</a></p>
</blockquote>

<p>Need to balance and understand: reduction, fiction, metaphor, emotions</p>]]></content><author><name>Pulkit Sharma</name></author><category term="personal" /><category term="learning" /><category term="books" /><summary type="html"><![CDATA[On Note Taking]]></summary></entry><entry><title type="html">Moving Back to Github Pages</title><link href="https://pulkit.cc/2024/12/02/back-to-github/" rel="alternate" type="text/html" title="Moving Back to Github Pages" /><published>2024-12-02T04:30:00+00:00</published><updated>2024-12-02T04:30:00+00:00</updated><id>https://pulkit.cc/2024/12/02/back-to-github</id><content type="html" xml:base="https://pulkit.cc/2024/12/02/back-to-github/"><![CDATA[<h1 id="back-to-github-pages">Back to Github Pages</h1>

<p>After experimenting with self hosting the blog on my rpi, I have moved the hosting back to Github pages.
One of the main reason has been the feeling that something was always “ON” in my home. Usually when I leave the house, I like to turn everything OFF. I don’t like the feeling of keeping the Rpi constantly running for a blog which barely has any visitors. I feel that is a waste of resources.
The Rpi was not doing anything compute heavy, I had no use case of a proper backend (the blog was still served using <code class="language-plaintext highlighter-rouge">jekyll serve</code>), so I did not find any need to continue using the Rpi, felt like an overkill to be honest.</p>

<p>A lot has changed since 2017, when I first started using Github pages for hosting this blog. Github Actions is now a mature product with full blown support for Jekyll. Migrating from Cloudflare to GH Pages for this domain (<code class="language-plaintext highlighter-rouge">pulkit.cc</code>) was straightforward. Since I had originally purchased this domain from Porkbun + I had no particular use of Cloudflare anymore, I decided to move the Nameservers back to Porkbun from Cloudflare.</p>

<p>After that I updated the <code class="language-plaintext highlighter-rouge">A</code> records to point to Github Pages’ servers. There was some errors in auto provisioning of the SSL certs (on Github’s end), which took a lot of time to debug. I was able to resolve it by adding a <code class="language-plaintext highlighter-rouge">CNAME</code> record for <code class="language-plaintext highlighter-rouge">www</code> which points to the original github pages domain: <code class="language-plaintext highlighter-rouge">pulkitsharma07.github.io</code>, all thanks to a random medium blog.</p>

<p>I removed the extra gimmicky stuff I had added in my about page (It used to print the Rpi temperature/uptime). Also removed the analytics around this blog. Sometime later I might add discourse comments to it.</p>

<h2 id="what-is-the-purpose-of-this-blog-">What is the purpose of this blog ?</h2>

<p>Reading my about page induced a feeling if cringe. And this happens every time. The longer the gap in reading my about page, the greater the cringe. I am still not fully sure about the purpose of this blog. My first post went to HN front page, and then 2 more after that. While writing all those I was pretty confident that these will get to the front page, as these are posts which I would have upvoted as a reader on HN.
And since then while writing any post, I wanted to write it for the HN audience. I wanted every post to “mean” something, to be HN worthy…I had and have many things I wanted to write, but I just couldn’t because I did not want to write about half baked, personal, stupid, unrelated, non-technical things… but I guess I should change that and not think too much..</p>]]></content><author><name>Pulkit Sharma</name></author><category term="personal" /><summary type="html"><![CDATA[Back to Github Pages]]></summary></entry><entry><title type="html">My Self Hosting Stack in 2023</title><link href="https://pulkit.cc/2023/05/04/self-hosting-blog/" rel="alternate" type="text/html" title="My Self Hosting Stack in 2023" /><published>2023-05-04T04:35:00+00:00</published><updated>2023-05-04T04:35:00+00:00</updated><id>https://pulkit.cc/2023/05/04/self-hosting-blog</id><content type="html" xml:base="https://pulkit.cc/2023/05/04/self-hosting-blog/"><![CDATA[<h1 id="why-self-host-">Why Self-Host ?</h1>
<ul>
  <li>Make use of the Raspberry Pi I had laying around.</li>
  <li>Experiment with some DevOps stuff.</li>
  <li>Feels cool to have a server running 24x7 in your home.</li>
</ul>

<h1 id="architecture">Architecture</h1>
<p>Wanted to keep this as simple as possible.</p>
<ul>
  <li>The Rpi is hooked directly into my wifi router using an ethernet cable.
    <ul>
      <li>The router is configured to assign a static private IP to the Rpi.</li>
    </ul>
  </li>
  <li><a href="https://developers.cloudflare.com/cloudflare-one/connections/connect-apps/#how-it-works">Cloudflare Tunnels</a> to expose the Rpi to the internet quite securely.
    <ul>
      <li>this is completely free ! (as of writing this)</li>
      <li>More details explained in the <code class="language-plaintext highlighter-rouge">Software</code> section below.</li>
    </ul>
  </li>
</ul>

<h2 id="pure-vs-impure-self-hosting">Pure vs Impure Self-Hosting</h2>
<p>I understand that relying on a third-party service like Cloudflare, is not actually self-hosting of the purest form. But I am okay with this impurity based on the time saved and features provided.</p>

<h1 id="hardware">Hardware</h1>

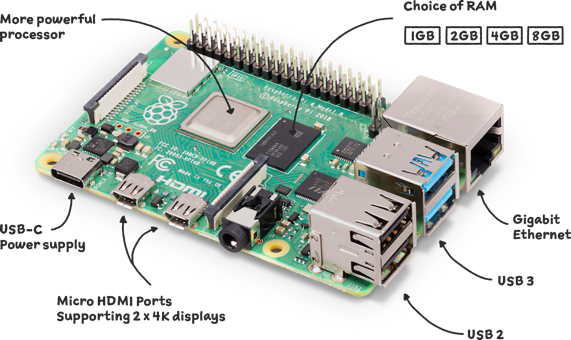
<figure class="half ">
  
    
      <img src="https://assets.raspberrypi.com/static/raspberry-pi-4-labelled-f5e5dcdf6a34223235f83261fa42d1e8.png" alt="Raspberry Pi 4B" />


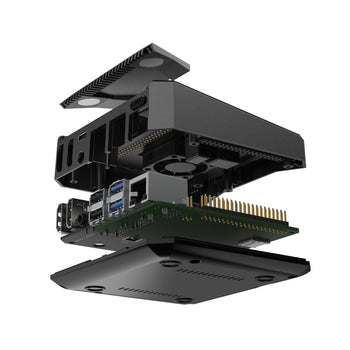
      <img src="https://cdn.shopify.com/s/files/1/0556/1660/2177/products/AR1-V2_04_350x.jpg" alt="Argon V2 Case" />


    <figcaption>Raspberry Pi 4B along with Argon V2 Case
</figcaption>
  
</figure>

<ul>
  <li>Raspberry Pi 4 Model B Rev 1.2
    <ul>
      <li>Has 4GB of RAM and 4 core 1.8 Ghz CPU</li>
      <li>Provisioned to run Raspbian OS (64-bit)
        <ul>
          <li>I am able to run almost all <code class="language-plaintext highlighter-rouge">arm64</code> docker images on the pi.</li>
        </ul>
      </li>
      <li>32 GB sdcard for persistent storage (SanDisk Extreme 32GB microSDHC UHS-3 Card)</li>
    </ul>
  </li>
  <li>Argon ONE V2 Case
    <ul>
      <li>Integrated fan really helps in keeping temperatures under control
        <ul>
          <li>Using <code class="language-plaintext highlighter-rouge">argonone-config</code> I can map fan speeds to different CPU temperatures.</li>
        </ul>
      </li>
      <li>Prevents dust build up</li>
      <li>All ports are neatly accessible on one side</li>
    </ul>
  </li>
</ul>

<h1 id="software">Software</h1>
<h2 id="development">Development</h2>
<p>I wanted to setup a development environment similar to the setup on my work Macbook. Here are few things:</p>
<ul>
  <li>Shell: zsh</li>
  <li>Editor/IDE: neovim (Specifically <a href="https://astronvim.com/">Astronvim</a>)
    <ul>
      <li>I had to compile neovim from source because there were no ARM v7 releases for that.</li>
    </ul>
  </li>
  <li>tmux
    <ul>
      <li>Pretty much standard to allow long running shell sessions.</li>
      <li>Can have native iTerm experience with <code class="language-plaintext highlighter-rouge">tmux -CC</code>. More info <a href="https://iterm2.com/documentation-tmux-integration.html">here</a></li>
    </ul>
  </li>
</ul>

<h2 id="hosting">Hosting</h2>
<ul>
  <li><a href="https://developers.cloudflare.com/cloudflare-one/connections/connect-apps/#how-it-works">Cloudflare Tunnels</a> do the heavy lifting for exposing the pi to the internet.
    <ul>
      <li>A daemon runs on the pi which opens a persistent connection with cloudflare infra. The cloudflare infra then receives requests from the internet and forwards them onto your pi via the daemon.</li>
      <li>You can expose multiple services via a single tunnel and also restrict public access via authentication.</li>
      <li>Watch <a href="https://www.youtube.com/watch?v=ZvIdFs3M5ic">this</a> for more info.</li>
      <li>A SystemD service unit file spawns the daemon on every boot.</li>
    </ul>
  </li>
  <li>Docker
    <ul>
      <li>I am running all my containers with <code class="language-plaintext highlighter-rouge">--restart=unless-stopped</code>. This will auto run the containers after boot. Check <a href="https://docs.docker.com/config/containers/start-containers-automatically/">this</a> for more info.</li>
    </ul>
  </li>
  <li>Deployment
    <ul>
      <li>I run <code class="language-plaintext highlighter-rouge">nginx:alpine</code> container which has the blog’s codebase mounted as a volume during runtime.</li>
      <li>Since this is a static website, I just go into the directory and do a <code class="language-plaintext highlighter-rouge">git pull</code> and the new version becomes active.</li>
    </ul>
  </li>
</ul>

<h2 id="monitoring-and-analytics">Monitoring and Analytics</h2>
<ul>
  <li><a href="https://plausible.io/docs/self-hosting">Plausible Analytics</a> running on the Pi to gather web analytics.</li>
  <li><a href="https://n8n.io/">n8n</a> is setup to monitor services and run other workflows
    <ul>
      <li>This is integrated with my Telegram account which acts as a central place to receive notifications</li>
      <li>I plan to add more workflows in the future for personal projects here.</li>
    </ul>
  </li>
  <li>Cloudflare Tunnel Notifications
    <ul>
      <li>This is a neat feature where you will get notified if pi loses internet connectivity.</li>
    </ul>
  </li>
  <li>For metrics I run <a href="https://prometheus.io/">Prometheus</a> on the pi to collect them with a retention of 30days
    <ul>
      <li>It can collect the pi metrics (temperature, cpu, ram, etc) and also collect metrics from the <a href="https://docs.docker.com/config/daemon/prometheus/">docker daemon</a> about running containers.</li>
      <li>Once I am able to get the hang of PromQL, I will be Using <a href="https://prometheus.io/docs/alerting/overview/">Alerts</a>.</li>
    </ul>
  </li>
  <li>Also I have a small script which periodically updates my <a href="/about/">about page</a> with my server’s stats.</li>
</ul>

<h1 id="future-work">Future Work</h1>
<p>Obviously the things documented in the blog are just the current state and these things will keep on evolving. Here are few things I have in mind:</p>
<ul>
  <li>Setup <a href="https://grafana.com/">Grafana</a> to create dashboards from prometheus metrics.</li>
  <li>Backups (probably using <a href="https://restic.net/">restic</a>)</li>
  <li>Related to the above, I thing I would like to look into is automating provisioning of the pi server(s) from scratch.
    <ul>
      <li>IMO the playbook or recipe based approaches are difficult to test from scratch, so I would prefer some “image” based approach (where I can change hostname etc).</li>
    </ul>
  </li>
  <li>Setup <a href="https://ikarus.sg/extend-sd-card-lifespan-with-log2ram/">log2ram</a> to buffer writes to the sdcard.</li>
</ul>]]></content><author><name>Pulkit Sharma</name></author><category term="software" /><summary type="html"><![CDATA[Why Self-Host ? Make use of the Raspberry Pi I had laying around. Experiment with some DevOps stuff. Feels cool to have a server running 24x7 in your home.]]></summary></entry><entry><title type="html">Why most Hacktoberfest PRs are from India</title><link href="https://pulkit.cc/2020/10/02/hacktoberfest-india/" rel="alternate" type="text/html" title="Why most Hacktoberfest PRs are from India" /><published>2020-10-02T09:35:00+00:00</published><updated>2020-10-02T09:35:00+00:00</updated><id>https://pulkit.cc/2020/10/02/hacktoberfest-india</id><content type="html" xml:base="https://pulkit.cc/2020/10/02/hacktoberfest-india/"><![CDATA[<blockquote>
  <p>A look into why most of the Hacktoberfest PRs are “manufactured” in India</p>
</blockquote>

<p><em>Before reading the post</em></p>

<p>Now that I have mentioned the name of a country in the title, please read the following points:</p>
<ul>
  <li>I am an Indian and have been living in the country since my birth.</li>
  <li>I do not claim to be right on all of this and there are many anecdotal generalisations here. Somethings are more like human problems instead of Indian problems <strong>but</strong> just the sheer number of people here puts India on everyone’s radar.</li>
  <li>This post is NOT to denigrate India. It is definitely critical of some of its social and psychological aspects. As a proof for that I want to mention that I am writing a series on the wisdom of ancient Indian philosophical ideas here: <a href="/2020/06/25/source-0/">Source [0]</a>, just so you know that I am not writing all my posts with the sole intention to show what is “wrong” with India. We should be brave enough to face the good and bad of it.</li>
  <li>It is a shame that I need to write this header in the first place. But the reality is with or without this, people will still get offended.</li>
</ul>

<hr />

<h2 id="index">Index</h2>

<ul>
<li><a href="#what">What</a></li>

<li><a href="#how">How</a></li>

<li><a href="#why">Why</a>
<ul>
  <li><a href="#the-signalling-problem">The Signalling Problem</a></li>
  <li><a href="#the-jugaad-mentality">The Jugaad Mentality</a></li>
  <li><a href="#computer-science-education-in-india">Computer Science Education in India</a></li>
  <li><a href="#but-why-for-hacktoberfest">But why for Hacktoberfest?</a></li>
  <li><a href="#the-problem-with-high-population-density">The problem with high population density</a></li>
  <li><a href="#hierarchy-of-needs">Hierarchy of Needs</a></li>
</ul></li>
<li><a href="#closing-thoughts">Closing Thoughts</a>
<ul>
  <li><a href="#probable-future">Probable Future</a></li>
  <li><a href="#improbable-future">Improbable Future</a></li>
</ul>
</li>
</ul>
<hr />

<h2 id="what">What</h2>

<p>As most of you may know, <a href="https://hacktoberfest.digitalocean.com/">Hacktoberfest</a> started on 1st October 2020. And as it with most things in human life, people came with <a href="https://mobile.twitter.com/shitoberfest">different</a> ways to hack hacktoberfest to get the free t-shirt.</p>

<p>Now apart from the sheer number of spam PRs which were opened, copious amount of time is being spent by the comparatively small number of open source maintainers who have comment, close and label each individual PR.</p>

<p>I became aware of this happening from this <a href="https://news.ycombinator.com/item?id=24643894">post</a>, and in a days time several more <a href="https://joel.net/how-one-guy-ruined-hacktoberfest2020-drama">posts</a> popped up. 
I got motivated (triggered?) to write this post when I saw the following on HN:</p>

<p><img src="/assets/hacktober/hn_comment.png" alt="hn-comment" class="img-responsive" /></p>

<p>After some investigation, I found the original claim to be true, <code class="language-plaintext highlighter-rouge">more than 60% of the spam PRs are coming from one country: India</code> and that is just 1 day after hacktoberfest started, I am sure the percentage will increase as days go by (unless DigitalOcean does something).</p>
<hr />

<h2 id="how">How</h2>

<p><a href="https://joel.net/how-one-guy-ruined-hacktoberfest2020-drama">This</a> post talks about one Indian YouTube channel which apparently told people to open spammy PRs. After I looked around some people were claiming he was falsely accused, anyways the video is deleted now, so I can’t comment on that.</p>

<p>Anyways, it didn’t take long and I was able to find few more Indian YouTubers who were pretty directly promoting ways to open PRs to get those sweet T-Shirts. One created his own <a href="https://github.com/seeditsolution/cprogram/pulls">repo</a> and encouraged people to google different programs and copy-paste them into a new PR against the empty repo.</p>

<p>I do not want to focus on the <em>How</em>, you will find find plenty videos/blogs on it, I am sure some Indian YouTuber has started working on creating a video on it.</p>
<hr />

<h2 id="why">Why</h2>
<p>One of the simplest explanation is that, DigitalOcean should have been very well anticipated that this is going to happen, after all they must have all the stats from the previous HacktoberFests.</p>

<p>We need to understand that Hacktoberfest is an marketing event. And all these spam and blogs posts around it is definitely serving their main purpose, there is no such thing as bad publicity indeed. Of course I could be totally wrong, all of this could be completely unintentional.</p>

<hr />

<p>Now, coming to the Indian side of the ongoing issue. Out of all the countries why does India have the most spammy PRs ? As a seasoned armchair philosopher, the following are my thoughts on the “Why” of all this.</p>
<hr />

<h3 id="the-signalling-problem">The Signalling Problem</h3>
<p>Whenever an online article/documentary/report claim to give a view into the “real” India, most of us (Indians) get offended.</p>

<p>I <em>was</em> in the bubble which was in the “offended” bucket for long time. The reason was simple: I, the people around me and the societal structures around me were all part of the same bubble. We do not have to worry about paying school fees or rent, we do not have worry about sending part of salary back home just so that our parents can buy groceries to survive..</p>

<p>I can go on and on, the overall gist is that I got offended in seeing what other people claim as “real” India, because that India was not part of my reality. Sure, I saw that when travelling from one place to another, saw that on news, read about that in the newspaper; but I was at a very safe distance from all of that.</p>

<p>These days, I try to not get offended when people say India has problem X or problem Y, because I realise I am living inside a cocoon where all of my needs are met, and one of the most serious issues my country is facing right now is <strike>witch-hunting </strike> nabbing the “drug mafia” amongst the Bollywood celebrities who allegedly murdered an actor by giving CBD oil (The absurdity of all this is unfathomable)</p>

<p>I mention all of this, because whenever I read posts which show India in some <a href="https://news.ycombinator.com/item?id=24552047">bad light</a>, there is always someone somewhere who gives anecdotes of how that is not true.</p>

<p>Here are some facts: we have a culture of <strong>extreme signalling</strong>. Signalling is the core building block of our society, most people don’t even realise that how big we are into signalling until they study about “signalling” as a phenomena and start becoming conscious of it. You notice that in the way your parents view you, how you make choices, how people around you make choices.</p>

<p>Of course, people will say “that is not an Indian problem, signalling is just a social construct and literally everyone does that on some level”. I am not denying not that, the very fact that I am writing this post is a kind of signalling I am doing.</p>

<p>It is well known fact that India is one of the densest countries on our <a href="https://ourworldindata.org/grapher/population-density?time=2017">planet</a>, extreme siginalling is just one of the consequences of the myriad social problems created by high population density. Signalling in an high density environment is now ever more important as the people you interact or the people who notice your activities/accomplishments are multiples higher than in any other place on the planet.</p>

<p>We people like the wear the “tightly knit society” as badge of honour, let me tell you this “tightly knit society” has done more harm than good. We Indian people have no India of the amount of mental harassment we all go through, because that is just normalized as being just phases of “life”.</p>

<p>The prevalence of extreme signalling brews the classic and infamous <em>herd mentality</em> in our minds. In middle school children have dreams to become a Pilot in the airforce, or maybe a Police officer, or maybe a Opera Singer ! But by the time of high school, everyone is just either on road to become an Engineer, a Doctor, a Lawyer, a Chartered Accountant …. or a <strong>failure</strong>. This may seem harsh but that’s how most of the society operates here in India.</p>

<p>Now once your track is chosen for you (or fortunately, if you get to choose the track), you have some set goals you “must” achieve because they guarantee monetary success with an extremely high probability. If you are Engineer, you need to get into IIT. If you are a Doctor, you need to get into AIIMS. If you are doing management, you need to get into IIM.</p>

<p>Now, if you are an Engineer then your success criteria is not just any IIT, it should be one of the top ones (Bombay, Delhi, Kharagpur, Roorkee) and not just any branch in IIT, it should be <em>Computer Science</em>. Because that’s how you get <a href="https://www.newindianexpress.com/nation/2019/dec/04/five-iitians-bag-pay-packages-of-over-rs-15-crore-2071120.html">Rs 1.5 crore “packages” (equivalent to 200K USD)</a>.</p>

<p>You can give me examples of how not all IIT toppers choose “Computer Science”, but that’s not the point, for the vast majority of people (more than a million), the success criteria is: getting Computer Science at IIT Bombay.</p>

<p>As might know (or have guessed) getting a seat in IIT Bombay is next to impossible for more than 99% people giving IIT, so they “lower” their goal by aiming for other IITs, but “Computer Science” remains the top priority.</p>

<h3 id="the-jugaad-mentality">The Jugaad mentality</h3>
<p>Hacking systems is so ingrained in our society that we have a word for it: <a href="https://en.wikipedia.org/wiki/Jugaad">Jugaad</a>. The whole scene with Hacktoberfest is just a demo of our Jugaad skills. Wait till you find out that <a href="https://indianexpress.com/article/india/inside-indias-fake-research-paper-shops-pay-publish-profit-5265402">most of the research papers</a> published in India are <a href="https://scroll.in/article/908230/indian-academics-lead-the-world-in-publishing-in-fake-journals-tarring-the-whole-education-sector">fake</a>. Even the orthodontist I was visiting for my checkup turned out to be fake and had forged her certificates (as told by by one other dentist).</p>

<p>The coaching industry actively promotes “cracking” these exams, and I am so tired writing on that topic that I do not want to write more about it here. Refer to my post on this <a href="https://www.linkedin.com/pulse/coding-interviewing-coaching-industry-prologue-pulkit-sharma?articleId=6662006663559684097">here</a>. Some children start joining these coaching classes from as low as 5th grade! (apart from doing regular school), just to be able to “crack” the IITs after 7-8 years !</p>

<p>Now how is coaching industry a Jugaad ? Simply because from the point of view of IITs, attending regular school should be enough to prep you for the exams (I think). These coaching industries have made the process significantly harder as you can’t even hope of getting a low tier IIT without attending the coaching classes.</p>

<p>The IIT coaching industry is minting fat cheques out of this entire situation, look at these ads on the front page of the news paper. These ads create a vicious cycle by reinforcing the core “signalling” construct of our society.</p>

<p><img src="/assets/hacktober/paper_1.png" alt="hn-comment" class="img-responsive" /></p>

<p><img src="/assets/hacktober/paper_2.png" alt="hn-comment" class="img-responsive" /></p>

<p><img src="/assets/hacktober/paper_3.png" alt="hn-comment" class="img-responsive" /></p>

<p>Do not quote me on this, but I think the IIT coaching industries make more <a href="https://www.businessinsider.in/education/news/iits-iisc-say-that-patchy-funding-is-delaying-institute-of-eminence-plans/articleshow/72103538.cms">money than the IITs</a> themselves. I understand the purpose of IITs is not to directly generate money, but if it would have more resources they can probably improve the infrastructure, employ better professors and improve the overall level of education.</p>

<h3 id="computer-science-education-in-india">Computer Science Education in India</h3>
<p>For vast majority of engineers in India, Computer Science is  one of the subjects you study in order to succeed in life. Just like you study Chemistry, you “study” Computer Science and once you learn all the “concepts”, you get a good job. (Apologies for so many quoted words, I can’t help putting them in quotes because they carry so much weight for me).</p>

<p>When people are in an average Indian college and if they are are lucky, information about some permutation/combination of the following is spread amongst the students: <em>Codechef, ICPC, DS/Algorithms, Infosys -&gt; road to USA, GSOC, Github,  Google, Facebook, 1.5cr “package”, MBA, MS in USA, .. yada yada yada</em>.</p>

<p>Of course this is not given by college authorities as they have no idea of the external world.</p>

<p>Us Indians are very good at following rules (or guidelines depending on the way you look at it), just tell us what to do, and we’ll do exactly that. We do not need any reasons or justifications for the most part, (we haven’t been taught that by the society). Just follow the rules and everything will be “set” for you is what everyone says and does. See a sample of how we learn to <a href="https://academia.stackexchange.com/questions/41687/what-is-behind-the-indian-undergrad-research-experience-spam">write emails</a> and prepare for <a href="https://www.geeksforgeeks.org/company-interview-corner/">software interviews</a></p>

<h3 id="but-why-for-hacktoberfest">But why for Hacktoberfest?</h3>

<p>Coming back to Hactkoberfest, it fell prey to the Jugaad nature of our existence. I personally know people who in-spite of being well paid software developers created dummy repos to create a circle of PR contributions for past Hacktoberfest events.</p>

<p>Of course, wherever there is any sort of incentive related to some metric, people will try to game that, whether that is LinkedIn connection counts, number of likes on Facebook or number of impressions on Instagram. There is nothing specifically Indian about it.</p>

<p>But there is one thing Indian that, the sheer number of people here who are out there to game everything which can give them some “profit”. The % of these people vary by their personal financial factors, perceived financial factors and of course the plethora of social constructs around them.</p>

<p>The problem is for most people gaming the system, that’s the actual system for them. They see hacking the system as part of the entire system itself. Things get so convoluted due to limited sources of information that people automatically think that hacking is just part of the process and something which is expected out of them. It’s a messy <a href="https://fs.blog/2020/06/coordination-problems/">coordination problem</a> that we have caught ourselves into.</p>

<p>The way of the jugaad is now applied to things unknowingly by people even when it is not really required. So far everything we have done needs some sort of Jugaad, so why would we not do that for getting t-shirts, getting into colleges, getting jobs, getting promotions, getting salary increments ?</p>

<p>After all the entire system is corrupt, right ? Everyone is corrupt, So why should <strong>I</strong> be the naive one and NOT try to actively game the system ? DigitalOcean is a big company, what would they lose if I just get one T-Shirt ?</p>

<p>^ That’s the thought process of a typical Indian developer.</p>

<h3 id="the-problem-with-high-population-density">The problem with high population density</h3>

<p>Everything mentioned so far can be in some sense applied to humans all around the world, but the amount of people in India makes things more complicated.</p>

<p>It complicates things because the society now has formalise / organise all this knowledge and information, which then slowly seeps itself into our <a href="https://en.wikipedia.org/wiki/Collective_unconscious">collective unconscious</a>. There is no overseer of this process, parents single-handedly pluck information from the collective unconscious and feed that to their children. And it’s <strong>NOT</strong> their fault, they are doing their best. If they knew what exactly to do, they wouldn’t have ended up in a dire situation in the first place, so of course they cannot rely on their own conscience, which I think is absolutely the right thing to do.</p>

<p>Once these ruleset(/guidelines) are plucked from the collective unconscious and are concretised by the news, media and society, then an individual cannot question them. Because why would you question them ? Millions of others are doing the same ? Are you claiming you are better than them by questioning the rules ? How will your parents get bread if you don’t study hard enough and get a job in the city ?</p>

<p>I want everyone reading this to understand that you have a privilege that, sorry to say, has blinded you about the real issues and problems we are facing. Most of the humans of our planet and by that, most of the humans living in India, are doing nothing wrong (from their own frame of reference), who am I or you to say what is Right or Wrong… for them? The situation gets so complex and intertwined that what is Right or Wrong for the other person takes the backseat, all that matters is what is Right or Wrong for me.</p>

<h3 id="hierarchy-of-needs">Hierarchy of Needs</h3>

<p>Armed with the wisdom from the unconscious all of us are ready, with just one mission: financial success. Trust me, when I say this, “Financial success” is what matters the most for us Indians. When I see someone who decides to push back “financial success” in order for other priorities, I have massive respect for them.</p>

<p>You need money to buy stuff, your family needs money to buy stuff; after all lack of money is our main source of unhappiness, right ? So keep your head down and just work towards that.</p>

<p>Trust me, I cannot begin to be thankful of the privilege I have in my life. My sole purpose of life is not just to be “financially successful” and provide resources for people around me. If I was part of the real India with the same name, intelligence, whatever, I would sure as hell be in a completely different situation where the only thing I would care about was earning money in order to satisfy the basic needs of me and people dependent on me.</p>

<p>When I say <code class="language-plaintext highlighter-rouge">basic needs</code> different thoughts can rise up, for some basic need is having just a house, for some basic need is a 3 bedroom house because they have their parents or grandparents to take care of, for some basic need is getting a job so they can get married and have children, for some it could be to just buy a car. In all, it is pretty subjective and you cannot convince people to let go of their basic needs, because for them, it is <strong>their basic</strong> need.</p>

<p>For the average software engineer aspirant in India, the basic need is to just get <em>any</em> 9-5 job. They don’t have the privilege to choose which company they want to work for, so they will join the first company which offers them a job.</p>

<hr />

<h2 id="closing-thoughts">Closing Thoughts</h2>

<p>It is without doubt that India has produced a lot of good programming talent and software, but we should not ignore the elephant in the room: <a href="https://economictimes.indiatimes.com/jobs/only-6-of-those-passing-out-of-indias-engineering-colleges-are-fit-for-a-job/articleshow/64446292.cms">most engineering graduates in India are not fit for hiring</a></p>

<p>People everywhere on this planet are just slaves of their circumstances and the societal constructs which surround them. When push comes to shove (which is the permanent state for most Indians), we only care about one thing, <strong>survival</strong>.</p>

<p>So, it doesn’t really matter how one gets a Hacktoberfest T-Shirt, as people don’t really have the conscience to see the consequences of doing that. As everyone around them is applying some Jugaad, so why not join the herd ?</p>

<h3 id="probable-future">Probable Future</h3>
<ul>
  <li>The probable future is simple to predict, the things which are happening today will keep on happening. This is a struggle for basic survival, and what others think takes the backseat in this game.</li>
  <li>Coding interviews will become harder. As I <a href="https://www.linkedin.com/pulse/coding-interviewing-coaching-industry-prologue-pulkit-sharma?articleId=6662006663559684097">mentioned in my post</a>, coaching industries will pop-up to help “crack” coding interviews, GSOC and maybe later HN posts. Trust me it is completely possible, all it takes is one Indian Google Engineer to create a YouTube video and say that he had X karma points on HN mentioned on his resume and that’s how his resume got shortlisted for Google.</li>
  <li>Big coaching industries in India have already started charging Rs.1500 for lessons on C++ STL. Without doubt, this will continue to happen on a larger and broader spectrum.</li>
  <li>YouTubers will continue to provide low quality tips and tricks for people.
    <ul>
      <li>
        <p>See what is happening to GSOC (I searched “GSOC” from a machine in Europe, to prevent geo based search results):
<img src="/assets/hacktober/gsoc.png" alt="hn-comment" class="img-responsive" /></p>
      </li>
      <li>
        <p>Even Google’s Foobar challenge is not spared:
<img src="/assets/hacktober/foobar.png" alt="hn-comment" class="img-responsive" /></p>
      </li>
    </ul>
  </li>
  <li>People will get offended on how I am denigrating Mother India. These people will questions my credentials and also point out that <code class="language-plaintext highlighter-rouge">I am not a thought leader of the industry</code> therefore all of my views are wrong by default.</li>
</ul>

<h3 id="improbable-future">Improbable Future</h3>
<ul>
  <li>Somehow people will realise that the metric they should focus on is the <em>love for computers</em>, <em>respect for other developers</em> and the <em>social impact of programming</em> on the world; not ranking in some programming contest, or number of Github contributors, or number of Github stars etc.</li>
  <li>Somehow good Indian software engineers will create quality content, blog posts and show what their actual job are like. They need to show that cutting edge software engineering happens not just in FAANG, but also in startups.</li>
  <li>Children in school have complete visibility and guidance on what lies ahead. Parents will stop projecting their own failures/insecurities in life on their children.</li>
  <li>Somehow Indian parents will become self sufficient, so that children are free to do and discover what they actually want.</li>
  <li>Failure is appreciated in society.</li>
</ul>

<p><em>Find discussion on HackerNews <a href="https://news.ycombinator.com/item?id=24667488">here</a>.</em></p>
<hr />]]></content><author><name>Pulkit Sharma</name></author><category term="india" /><category term="software" /><summary type="html"><![CDATA[A look into why most of the Hacktoberfest PRs are “manufactured” in India]]></summary></entry><entry><title type="html">Source [1] - Bubbles</title><link href="https://pulkit.cc/2020/06/28/source-1/" rel="alternate" type="text/html" title="Source [1] - Bubbles" /><published>2020-06-28T09:35:00+00:00</published><updated>2020-06-28T09:35:00+00:00</updated><id>https://pulkit.cc/2020/06/28/source-1</id><content type="html" xml:base="https://pulkit.cc/2020/06/28/source-1/"><![CDATA[<blockquote>
  <p>This essay is in continuation of <a href="/2020/06/25/source-0/">Source [0]</a></p>
</blockquote>

<p>We all are vaguely familiar with the concepts of bubbles. Bubbles in the sense that each one of us is present in them and that bubble dictates which kind of information you consume, love, hate, and such. Bubbles can also be called a belief system. A belief system is not just about whether you believe in god or not, but it just tells in a broad sense what one believes about everything.</p>

<p>As we grow up, we metaphorically also keep growing our bubble by having new experiences, meeting new people, going to new places, discovering new knowledge to state a few.</p>

<p>Bubbles are generally used in a negative sense, for example, “That person seems to live in a bubble, he does not care about politics”, but bubbles are very helpful.
You see, we are unconsciously aware of this fact, you may not call it a bubble or not even call it anything, but you know everyone (including you) has a bubble. And it’s just not people, we also put non-living things in a bubble. Like a religious book almost always gets put in a dogmatic bubble.</p>

<p>By putting things and people inside their own bubble, our mind now takes the call as to whether it makes sense to read/question/argue/understand something/someone or not. It does this decision making by seeing your own bubble and the other thing’s bubble, if they both align, i.e. they share some common beliefs, then the mind can allow us to continue, otherwise, the mind thinks that doing the activity in question will be a waste of time and energy.</p>

<p>There are many positive benefits of doing this, that’s how we have diverse thoughts, things, and persons. If the mind does not do it, countless amounts of energy will be spent by people in doing things that they don’t really require in some sense.</p>

<p>Conventional schooling systems do the same thing, they try to stop this automatic decision-making process of mind and forces us in doing things which don’t really matter in the long run. You are not allowed to question why you are studying a particular subject. A counterargument to this can be that during childhood our bubbles are not mature enough, hence the way the schooling system is designed. My counterargument to that is, in retrospect, I do not think it managed to change my bubble significantly or increase the rate of how my bubble grew, at best it created a false impression for me (and the education system) that it grew bigger by passing exams which test regurgitation abilities.</p>

<p>We have seen the positives of how the prioritization process of aligning bubbles done by our brain, that is it helps us in saving time and energy and helping us to grow, now it is time to see some downsides of that process.</p>

<p>One important point to note that this decision process (of choosing which bubbles are good/bad for you) is not always a conscious process, it can be seen a long-running process in the subconscious mind which sometimes comes into the conscious realm. Whenever you think you make a decision, it’s a conscious process, in other cases, your mind is making a lot of decisions subconsciously.</p>

<p>Let’s see an example, consider a person who is not interested in science and related topics as they consider these things to be “hard”. That person now sees a video on YouTube titled: “Deep Dive into our Universe”, chances are very low that a person will attempt to watch that video, as the decision would unconsciously have been made by the mind. There is a  caveat, due to the way modern internet operates, they will probably not even get into this situation as the recommendation algorithms will rarely show this content to the person. The internet giants have a better understanding of what your bubble is (better than we know it ourselves), therefore it will show you content that aligns with your bubble so that you consume it and then they can make money off ads. I am not saying that I have a better alternative, just stating the facts so you know how they operate by representing our bubbles via machine learning systems, using extensive monitoring/tracking.</p>

<p>Consider that this person had the option to watch the video, but they did not, reasons can be that they thought that they would not be able to understand, why to spend time in it, how does this help me, and similar thoughts. Here’s a fact, they might be completely right, watching this video may really not serve any purpose to them. In this way, bubble based judgments are really helpful in most cases.</p>

<p>But let us consider another possibility, that they did watch the video, and it turns out that the video was deeply instructional in nature. They thought they would not understand any of it, but after watching some part of it they understood 20% of the content. That’s a great thing!</p>

<p>So, there is always a possibility that something that our mind clearly ignores or does not give much more thought to, it is possible that there is more meaning present there. To look at the extra meaning, you need to put in a conscious effort to discover or extract it.</p>

<p>“Effort” is an interesting word, from the following which thing takes more effort? watching a 1-hour movie, or 1-hour video of a college lecture. Again, if the lecture is in a subject you are interested in (i.e. aligns with your bubble) you may need almost zero effort to watch the lecture, but as you may know, it takes considerable effort to watch the lecture video if it does not align with your bubble, and most probably you won’t watch it entirely, unlike in an actual lecture where you would have to sit through it even after you decide to stop making the effort to understand it, just to keep your physical self present in the lecture hall.</p>

<p>Coming back to the judgment aspect of it, I want to give another personal example. Sometime back I wrote about a particular company charging too much for coding related courses, one of the comments from a major stakeholder in that company said: “You are making these claims as if you are intellectual thought leader of the country”.  Obviously he was projecting what kind of bubble I need to belong to make sense to him, instead of looking at what I said and countering that.</p>

<p>I see this is a major problem that limits all of us to new ideas, every time I have a judgment about something, I try to think, is that because of what someone said, or is that because who said it, or is it a mixture of both cases.  I saw an interesting comment on YouTube on a video, it said: “A debate should not be about who is right, but what is right”.</p>

<p>Now, let us resume from where we left in <a href="/2020/06/25/source-0/">Source [0]</a>. For the sake of clarity, I am going to reiterate our established common ground.</p>
<ol>
  <li>Philosophy is not just about talking in the air, it can contain some meaning which can in turn help us in widening our perspectives.</li>
  <li>Most religions have an essence that is deeply philosophical.</li>
  <li>In the case of India, a large number of sages spoke of deep philosophical concepts.</li>
  <li>We have a set of belief systems or bubbles in place which help in consuming things that align with who we are, but on the other hand, it can also prevent us from discovering something new.</li>
</ol>

<p>If you have reached so far, I hope that this content is aligning with you, so the purpose of writing this is fulfilled, I hope you continue reading but as a cautionary warning, I want to mention the target audience of this particular series of blogs for the future posts.</p>

<p>Without digressing too much, I want to point out that there are several views on the <a href="https://en.wikipedia.org/wiki/Meaning_of_life#Popular_views">meaning of life</a>, one view says that the meaning of life is to do <em>good things</em>, another says that the meaning of life is to <em>achieve one’s true potential</em>. The one view which I relate to a lot is the view that meaning of life is to <em>gather knowledge and wisdom</em>.</p>

<p>By saying that, I am not claiming that other views are in some sense of lower stature than the view of <em>knowledge</em>. I just state that so that you can see which bubble I belong to (and in turn this series of blogs), this will help you in judging whether you want to spend more time reading it or not.</p>

<p>With this in mind, I just want to point out that I have often found that expanding our own bubble never hurts and something good often comes out of it. For instance, reading the Bible would not magically convert you into a Christian, you’ll just create your own interpretation of what it is written in it, which will definitely give you a fresh perspective on the world i.e. expand your bubble.</p>

<p>In the next blog post, I will attempt to introduce you to some concepts related to the study of the nature of god and consciousness in ancient Indian philosophy, hopefully, the bubbles align and help in expanding yours.</p>]]></content><author><name>Pulkit Sharma</name></author><category term="philosophy" /><category term="random" /><category term="india" /><category term="history" /><summary type="html"><![CDATA[This essay is in continuation of Source [0]]]></summary></entry><entry><title type="html">Source [0]</title><link href="https://pulkit.cc/2020/06/25/source-0/" rel="alternate" type="text/html" title="Source [0]" /><published>2020-06-25T09:35:00+00:00</published><updated>2020-06-25T09:35:00+00:00</updated><id>https://pulkit.cc/2020/06/25/source-0</id><content type="html" xml:base="https://pulkit.cc/2020/06/25/source-0/"><![CDATA[<blockquote>
  <p>Series of essays exploring Indian Philosophy/Sprituality</p>
</blockquote>

<p>I’ll start with a word: <strong>Dissatisfaction</strong>. It is a word most of us try to run away from. We do not want to feel dissatisfied. Why do we not want to feel dissatisfied, but we are okay with feeling satisfied?
Is life full of satisfaction with small pieces of dissatisfaction in between (like raisins on a cookie), or the other way round, wherein life is full of dissatisfaction inside which we find small moments of satisfaction. Or the extremes like, life is either just dissatisfaction or just satisfaction.
These statements are pretty obvious but can be inspected a bit more (As later you will see this process of continuous inspection leads us to some uncharted territories).</p>

<p>These are important questions. The importance of something is of course subjective, so let’s assume them to be important for the sake of reading this text.</p>

<p>A possible reaction for a layperson while reading so far maybe: this guy (me, writer) is depressed about life, or some thought close to this in a similar direction.
The reason why I say so, is because I would (could?) react in a similar manner. Whenever someone writes about something so-called “sad”, the knee jerk reaction is, “this person must’ve been through something difficult”. It is an important point to consider.</p>

<p>Another possible reaction is: Why is all this important? What is your point? Why are you making pointless statements/questions?
Again, these are possible reactions, but just for the sake of reading this text, let’s assume that you may find something useful here.</p>

<p>Now that we’ve loaded a big pile of assumptions, I’ll come to the central point of this text.</p>

<p>Let’s look at some facts, most of our modern education/upbringing is orchestrated in a way that places importance on our external existence. And this has brought us tremendous success/results. Human life expectancy has drastically increased in the past 200 years, and of course, with the advent of the internet, we have started to innovate more rapidly.</p>

<p>Now the age-old question, have we become happier? Since this question can be cringe-inducing, let’s look at it from a different perspective.</p>

<p>From the human evolutionary standpoint, the modern world which we see ourselves in has been around for a minute fraction of the entire human existence (Homo Sapiens have been around for about 500,000 years).</p>

<p>And we have not grown any smarter, in the sense that our brain has not evolved in the past 50,000 years or so. Of course, here my assumption is that our smartness is proportional to the size of our brain.</p>

<p>This fact raises a question: if we assume that we have the same intellectual capacity for the past 50,000 years, why did modern science only emerge recently, i.e. in the past 2000 years, why did all this not happen any earlier? Why did we discover nuclear power now and not 30,000 years ago?</p>

<p>Another way to look is, what were the people before our modern age doing with their life (when they had the same intellectual capacity).</p>

<p>These are treacherous grounds I am entering here. You may notice that I did not use the term IQ, instead, I went ahead with something like “intellectual capacity” in order to comment quantifiably on our ancestor’s intelligence. The thing to note here is that IQ (or any other measure of intelligence) is a modern way to measure modern intelligence, so it can not be applied to them (humans thousands of years ago).</p>

<p>To give an example, the human species survived and evolved for millions of years all without the presence of spoken language, is that not sufficient display of intelligence? A million years is an unfathomable duration of time.</p>

<p>It is difficult to comment (from my uneducated perspective) what were the intellectual pursuits of our ancestors. We definitely see the beginnings of religions/cults at that time, as a way to organize and create a system of information distribution glued together by doctrines and dogmas.</p>

<p>What I can comment on is what people in ancient India did.</p>

<p>Before that let’s take a small detour to understand philosophy, to establish some common ground.</p>

<p>Philosophy is often misunderstood as “talking in the air” or air talk. One way I think about philosophy is that any questions/statements that cannot be answered literally or create a feeling of profoundness or create a deeper need for further inspection, can be considered as philosophical. You can obviously find better definitions in other resources, I am not a philosopher.</p>

<p>With our modern age, India’s philosophical history is tied very deeply with religion, even ingrained in it. In fact, it’s not just about India, most of the modern religions are deeply philosophical in essence.</p>

<p>Coming back to ancient India, you may already know that India was a country of sages, who were deeply revered. I do not feel hesitation in saying that these sages are what can be called philosophers in modern-day. But since they wear saffron and pray to some god, their statements/teachings are consumed very rarely by non-religious people, I will go one step further and say that these teachings are not even understood clearly by most religious people.</p>

<p>Which brings us to the questions, why should we even listen to these great ancient philosophers? What “knowledge” can they have which can be applied to our modern world, which is so drastically different from ancient times? How can these philosophers say something which can apply to me?</p>

<p>I believe these questions are completely valid, and I will talk about them later in further posts.</p>

<p><em>References</em></p>
<ul>
  <li><a href="https://advances.sciencemag.org/content/4/1/eaao5961#:~:text=Our%20data%20show%20that%2C%20300%2C000,100%2C000%20and%2035%2C000%20years%20ago.">Evolution of Modern Human Brain Shape</a></li>
  <li><a href="https://en.wikipedia.org/wiki/Indian_philosophy">Wikipedia: Indian Philosophy</a></li>
  <li><a href="https://en.wikipedia.org/wiki/Life_expectancy">Wikipedia: Life Expectancy</a></li>
</ul>

<blockquote>
  <p>Next post in continuation of this: <a href="/2020/06/28/source-1/">Source [1] - Bubbles</a></p>
</blockquote>]]></content><author><name>Pulkit Sharma</name></author><category term="philosophy" /><category term="random" /><category term="india" /><category term="history" /><summary type="html"><![CDATA[Series of essays exploring Indian Philosophy/Sprituality]]></summary></entry><entry><title type="html">Managing Shell Commands through Vim</title><link href="https://pulkit.cc/2018/08/08/managing-shell-commands/" rel="alternate" type="text/html" title="Managing Shell Commands through Vim" /><published>2018-08-08T22:00:00+00:00</published><updated>2018-08-08T22:00:00+00:00</updated><id>https://pulkit.cc/2018/08/08/managing-shell-commands</id><content type="html" xml:base="https://pulkit.cc/2018/08/08/managing-shell-commands/"><![CDATA[<blockquote>
  <p>A look at into how I used Vim to notes about frequently used shell commands at my new job</p>
</blockquote>

<p>Before I joined my job, I had been a heavy Windows user. Apart from the “UNIX Programming” course in college, I had barely used any of the shell commands.</p>

<p>In the initial days of the job, in order to run a previously executed shell command, I used to press the up arrow key on the keyboard to search for it.</p>

<h2 id="shell-reverse-search">Shell Reverse Search</h2>

<p>Turns out there is a neat way to search through your previously executed shell commands (All executed commands are stored in the bash history, for <code class="language-plaintext highlighter-rouge">zsh</code> it is the <code class="language-plaintext highlighter-rouge">~/.zsh_history</code> file).
All you have to do is press <kbd>CTRL</kbd>+<kbd>r</kbd> and then type some parts of the commands that you can recall.</p>

<p>For instance, if I know that sometime back, I had used a command to figure out the role of a particular Redis instance. Then all I have to do is <code class="language-plaintext highlighter-rouge">&lt;ctrl-r&gt;role</code> and the desired command while appear automagically !! (Keep pressing <code class="language-plaintext highlighter-rouge">&lt;ctrl-r&gt;</code> to cycle through the results)</p>

<p><img src="/assets/casts/reverse_search.svg" alt="reverse-search" class="img-responsive" /></p>

<h2 id="aliases">Aliases</h2>

<p>One day, I was looking at my co-worker’s laptop while he was debugging some issue, and he started typing mysterious commands in the terminal like <code class="language-plaintext highlighter-rouge">gco master</code>.
Turns out <code class="language-plaintext highlighter-rouge">zsh</code> comes with a set of <code class="language-plaintext highlighter-rouge">aliases</code>, which are like shortcuts to entire shell commands.<code class="language-plaintext highlighter-rouge">gco</code> is an alias for <code class="language-plaintext highlighter-rouge">git checkout</code>. If you feel that there is a command that you need frequently, it is a good idea to make an alias for it. This avoids typing the entire command, and you can always reverse search for the alias, as it should be easy to remember.</p>

<p>To see existing aliases, you can run <code class="language-plaintext highlighter-rouge">alias -L</code>. Creating a new alias is as simple as adding</p>

<div class="language-sh highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nb">alias </span><span class="nv">ping_redis</span><span class="o">=</span><span class="s1">'redis-cli -h 100.100.100.100 ping'</span>
</code></pre></div></div>
<p>to your rc file (For <code class="language-plaintext highlighter-rouge">zsh</code> it is primarily <code class="language-plaintext highlighter-rouge">~/.zshrc</code>).</p>

<hr />

<p>As you keep using the terminal, it may happen that you need some commands which are infrequently used but are important. For example one time configuration commands, installation steps, or some important queries to your database.</p>

<p>Making an alias does not make sense for each of these commands as they are not frequently used and you’ll get overloaded with aliases to remember. Reverse search might not work if you don’t remember any part of the command (or the bash history file got deleted/truncated).</p>

<p>I often found out that I had important commands scattered in different documents. Some of them might be in the OS X Notes app, some in an always running Sublime Text window or some found out by grepping <code class="language-plaintext highlighter-rouge">~/.zsh_history</code>.</p>

<p>Once, I would’ve found the command; the next step was to copy, go to the terminal window, paste and execute that command.</p>

<h2 id="vim">Vim</h2>
<p>Why not use Vim?</p>

<p>For me, I keep a <code class="language-plaintext highlighter-rouge">commands.sh</code> file to take notes regarding all the important commands and use a handy little setting in the vimrc file to execute those commands from the file itself. Check out the demo…</p>

<p><img src="/assets/casts/commands_vim_demo.svg" alt="commands-demo-vim" class="img-responsive" /></p>

<p>You can select the appropriate shell command in <code class="language-plaintext highlighter-rouge">visual</code> mode and run them by pressing <code class="language-plaintext highlighter-rouge">r</code></p>

<p>Here are the appropriate vimrc settings for <code class="language-plaintext highlighter-rouge">zsh</code>. I had to do some digging on StackOverflow to get it to load my aliases.</p>

<div class="language-vim highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">set</span> <span class="k">shell</span><span class="p">=</span>zsh
vnoremap <span class="k">r</span> <span class="p">:</span><span class="s1">'&lt;,'</span><span class="p">&gt;</span><span class="k">w</span> <span class="p">!</span>zsh
</code></pre></div></div>

<p>You need to ensure that your aliases are in <code class="language-plaintext highlighter-rouge">.zshenv</code>, or you can make <code class="language-plaintext highlighter-rouge">.zshenv</code> a symlink to <code class="language-plaintext highlighter-rouge">.zshrc</code>.</p>

<p>Keeping the shell commands in <code class="language-plaintext highlighter-rouge">commands.sh</code> will allow you to write commands that you can later automate.
For instance, if you repeatedly SSH into a machine to run something in the Rails console, you can keep the following in your <code class="language-plaintext highlighter-rouge">commands.sh</code> file instead:</p>

<div class="language-sh highlighter-rouge"><div class="highlight"><pre class="highlight"><code>ssh <span class="nt">-t</span> 100.100.100.100 <span class="s2">"cd /some/dir/rails/;bundle exec rails console staging &lt;&lt;&lt; 'Trash.delete_all'"</span>
</code></pre></div></div>

<hr />

<p><strong>What are your thoughts? How do you manage the growing set of commands you work with?</strong></p>

<p>A neat way I found out today was to use comments to tag shell commands.
For example:</p>

<div class="language-sh highlighter-rouge"><div class="highlight"><pre class="highlight"><code>find <span class="nb">.</span> <span class="nt">-name</span> <span class="s2">"*.sh"</span> <span class="c">#find shell scripts</span>
</code></pre></div></div>

<p>Once you execute the above, you can reverse search by doing <code class="language-plaintext highlighter-rouge">find shell scripts</code>.
Sweet!</p>

<h3 id="helpful-resources">Helpful Resources:</h3>
<ul>
  <li><a href="https://stackoverflow.com/questions/2575545/vim-pipe-selected-text-to-shell-cmd-and-receive-output-on-vim-info-command-line/5373376#5373376">https://stackoverflow.com/questions/2575545/vim-pipe-selected-text-to-shell-cmd-and-receive-output-on-vim-info-command-line/5373376#5373376</a></li>
  <li><a href="https://unix.stackexchange.com/questions/113462/how-can-i-make-shell-aliases-available-when-shelling-out-from-vim/197135#197135">https://unix.stackexchange.com/questions/113462/how-can-i-make-shell-aliases-available-when-shelling-out-from-vim/197135#197135</a></li>
  <li><a href="https://unix.stackexchange.com/questions/26245/how-to-quickly-store-and-access-often-used-commands/26263#26263">https://unix.stackexchange.com/questions/26245/how-to-quickly-store-and-access-often-used-commands/26263#26263</a></li>
</ul>]]></content><author><name>Pulkit Sharma</name></author><category term="shell" /><category term="vim" /><category term="learning" /><summary type="html"><![CDATA[A look at into how I used Vim to notes about frequently used shell commands at my new job]]></summary></entry><entry><title type="html">Using Jekyll and Github Pages (in 2017)</title><link href="https://pulkit.cc/2017/09/23/using-jekyll-and-github-pages/" rel="alternate" type="text/html" title="Using Jekyll and Github Pages (in 2017)" /><published>2017-09-23T13:13:34+00:00</published><updated>2017-09-23T13:13:34+00:00</updated><id>https://pulkit.cc/2017/09/23/using-jekyll-and-github-pages</id><content type="html" xml:base="https://pulkit.cc/2017/09/23/using-jekyll-and-github-pages/"><![CDATA[<blockquote>
  <p>After reading numerous posts online for using Jekyll and Github Pages together, I faced couple of issues. Lets take a look and see how I addressed some of them.</p>
</blockquote>

<ul>
  <li>Jekyll 3 now recommends using Gem-based themes. I was not able to find themes other than the ones mentioned <a href="https://github.com/planetjekyll/awesome-jekyll-themes">here</a>.</li>
  <li>The ones <a href="https://pages.github.com/themes/">supported</a> by Github are not exactly blog like.</li>
</ul>

<p>After spending considerable amount of time looking for a perfect theme (And giving up numerous times). I decided to go with the <code class="language-plaintext highlighter-rouge">whiteglass</code> theme.</p>

<p>I cloned the repo and had the blog running locally, it was time to push to my <code class="language-plaintext highlighter-rouge">.github.io</code> repo. After, refreshing 3-4 times all I was staring at was a blank white screen. Soon, I got a mail from Github regarding a build warning.</p>

<p><em>You are attempting to use a Jekyll theme, “jekyll-whiteglass”, which is not supported by GitHub Pages</em></p>

<h2 id="the-fix">The Fix</h2>

<p>Instead of serving a Jekyll Project directly from the <code class="language-plaintext highlighter-rouge">master</code> branch of the <code class="language-plaintext highlighter-rouge">github.io</code> repository, we can instead serve the static files generated from the <code class="language-plaintext highlighter-rouge">jekyll build</code> command, i.e. the contents of the <code class="language-plaintext highlighter-rouge">_site</code> directory.
This way, we will remove dependency on Github Pages to build the Jekyll Project, instead it will only serve the static pages.</p>

<p>Since, the <code class="language-plaintext highlighter-rouge">master</code> branch will have the “built” website, where should we store the actual Jekyll Project ?</p>

<p>In my case I have stored it in the <code class="language-plaintext highlighter-rouge">development</code> branch inside the same repository. I will work on the blog in this branch and will push the built website to the <code class="language-plaintext highlighter-rouge">master</code> branch. I have seen some repositories where people have written Travis jobs to do this exact thing. I feel that is an overkill, a slow process and downright exploitation of a free service. Please correct me if I am wrong.</p>

<p>I have written a small shell script which will build the website and push the changes to the <code class="language-plaintext highlighter-rouge">master</code> branch. Here it is:</p>

<div class="language-sh highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c">#! /bin/sh</span>

<span class="nv">BUILD_DIR</span><span class="o">=</span><span class="s2">"./_site"</span>
<span class="nv">TMP_DIR</span><span class="o">=</span><span class="s2">"/tmp/jekyll_build"</span>
<span class="nv">CURRENT_BRANCH</span><span class="o">=</span><span class="si">$(</span>git rev-parse <span class="nt">--abbrev-ref</span> HEAD<span class="si">)</span>

<span class="c"># Delete old build files if any</span>
<span class="nb">rm</span> <span class="nt">-rf</span> <span class="nv">$BUILD_DIR</span>

<span class="c"># Build</span>
bundle <span class="nb">exec </span>jekyll build

<span class="c"># If Build succeeds</span>
<span class="k">if</span> <span class="o">[</span> <span class="nt">-d</span> <span class="s2">"</span><span class="nv">$BUILD_DIR</span><span class="s2">"</span> <span class="o">]</span><span class="p">;</span> <span class="k">then
    </span><span class="nb">echo</span> <span class="s2">"JEKYLL: BUILD SUCCESS"</span>
    <span class="nb">rm</span> <span class="nt">-r</span> <span class="nv">$TMP_DIR</span>

    <span class="c"># Move BUILD_DIR to /tmp</span>
    <span class="nb">mv</span> <span class="nv">$BUILD_DIR</span> <span class="nv">$TMP_DIR</span>

    <span class="c"># Change branch to master</span>
    <span class="k">if </span>git checkout master<span class="p">;</span> <span class="k">then
      </span><span class="nb">echo</span> <span class="s2">"SUCCESSFULLY SWITCHED TO MASTER"</span>

      <span class="c"># Cleanup</span>
      <span class="nb">ls</span> | xargs <span class="nb">rm</span> <span class="nt">-r</span>

      <span class="c"># Get the build</span>
      <span class="nb">mv</span> <span class="nv">$TMP_DIR</span>/<span class="k">*</span> <span class="nb">.</span>

      <span class="c"># Commit</span>
      git add <span class="nb">.</span>
      git commit <span class="nt">-m</span> <span class="s2">"Deploy </span><span class="si">$(</span><span class="nb">date</span><span class="si">)</span><span class="s2">"</span>
      <span class="k">if </span>git push origin master<span class="p">;</span> <span class="k">then
        </span><span class="nb">echo</span> <span class="s2">"DEPLOYED SUCCESSFULLY !"</span>
        <span class="nb">echo</span> <span class="si">$(</span><span class="nb">basename</span> <span class="si">$(</span>git remote show <span class="nt">-n</span> origin | <span class="nb">grep </span>Fetch | <span class="nb">cut</span> <span class="nt">-d</span>: <span class="nt">-f2-</span><span class="si">))</span>
      <span class="k">else
        </span><span class="nb">echo</span> <span class="s2">"DEPLOY FAILED !"</span>
      <span class="k">fi
    else
      </span><span class="nb">echo</span> <span class="s2">"CANNOT SWITCH BRANCH, ABORTING"</span>
    <span class="k">fi

else
    </span><span class="nb">echo</span> <span class="s2">"JEKYLL: BUILD FAILURE"</span>
<span class="k">fi

</span>git checkout <span class="nv">$CURRENT_BRANCH</span>
</code></pre></div></div>
<p>This script lives in the <code class="language-plaintext highlighter-rouge">development</code> branch.</p>

<p>After I am done doing my changes to the blog. I push them to the <code class="language-plaintext highlighter-rouge">development</code> branch, and then do <code class="language-plaintext highlighter-rouge">./deploy</code>. The script will then make a new commit on <code class="language-plaintext highlighter-rouge">master</code> having your latest masterpiece.</p>

<h2 id="why-i-dont-like-the-gem-based-themes">Why I don’t like the gem based themes.</h2>

<p>I have added the <code class="language-plaintext highlighter-rouge">deploy</code> script as a post-commit hook, but unfortunately some changes do not require a commit.</p>

<p>This is because most of the theme related code is now inside the gem’s directory (i.e. not inside my git repo). So, say If I want to change the Google Analytics tracking script, then I’ll need to do the changes in the <code class="language-plaintext highlighter-rouge">google_analytics.html</code> file. Since, this file is inside the gem’s directory (in my case at <code class="language-plaintext highlighter-rouge">/Users/pulkit/.rvm/gems/ruby-2.2.5/gems/jekyll-whiteglass-1.3.0/_includes/</code>), I cannot make a commit on <code class="language-plaintext highlighter-rouge">development</code> to reflect this change.</p>

<p>Gem based themes are good for people who are new to Jekyll and do not wish to modify the themes they use. Since, most of the theme related code is now present in some other directory, users will not be overwhelmed from the directory structure when they do <code class="language-plaintext highlighter-rouge">jekyll new</code>.
But sooner or later, you’ll need to make some changes to the theme (changing the font size for example). Doing those changes in some other directory and not inside version control is pretty cumbersome and will hurt in the future.</p>

<p><strong>UPDATE</strong>: Found out this <a href="https://jekyllrb.com/docs/themes/#converting-gem-based-themes-to-regular-themes">https://jekyllrb.com/docs/themes/#converting-gem-based-themes-to-regular-themes</a>, this will make your git repo to have all the code ! But then, what is the point of gem-based themes ?</p>

<p><em>Discussion on <a href="https://news.ycombinator.com/item?id=15354908">HackerNews</a>.</em></p>]]></content><author><name>Pulkit Sharma</name></author><category term="development" /><summary type="html"><![CDATA[After reading numerous posts online for using Jekyll and Github Pages together, I faced couple of issues. Lets take a look and see how I addressed some of them.]]></summary></entry></feed>